DeepSeek releases V4.1 Flash with native multimodal vision, 552B MoE and lower API rates
DeepSeek has launched DeepSeek-V4.1-Flash, a 552B-parameter mixture-of-experts model featuring a novel Causal Encoder–Decoder architecture with just 8B active input and 16B active output parameters. The release brings native vision, compresses KV cache storage by up to 8x, and slashes off-peak API pricing to $0.15 per million input tokens.
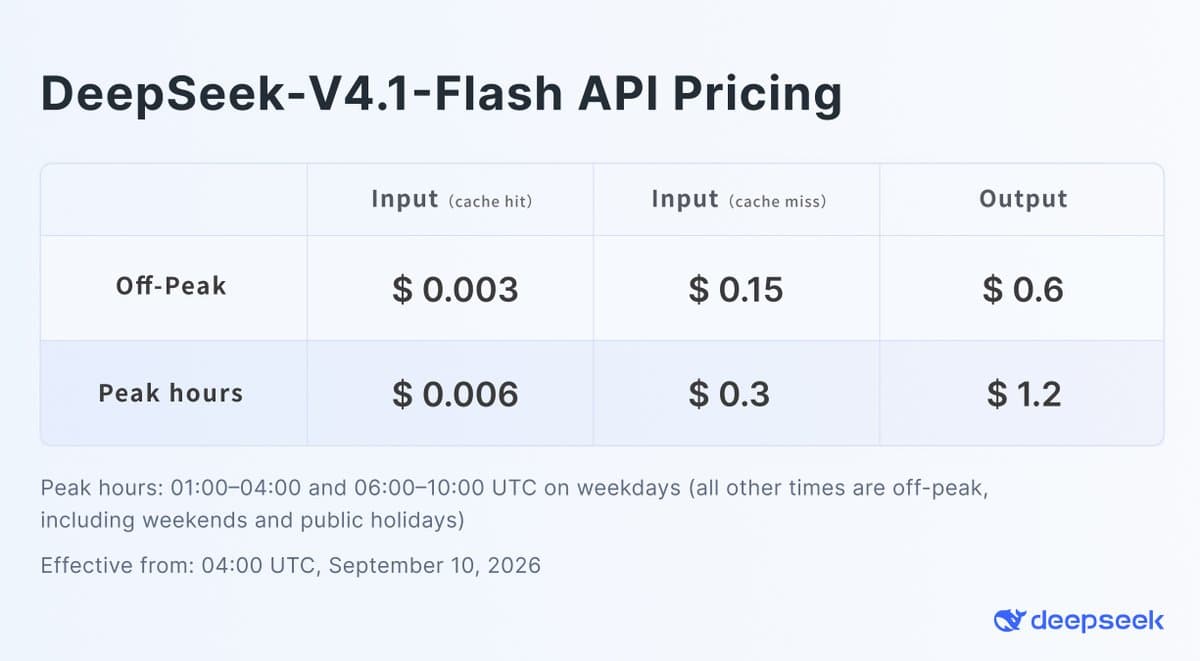
Active 17 hours/day Mon–Fri + all 24 hours Sat & Sun (UTC). Cache hit achieves 98% discount at $0.003/M.
Active Mon–Fri during UTC 01:00–04:00 and 06:00–10:00 (7 peak hours/weekday).
| Platform | Route Identifier | Context | Max Output | Rate / Tier | Status |
|---|---|---|---|---|---|
| Official DeepSeek API | deepseek-flash | 1.05M tokens (1,048,576) | 384K tokens (384,000) | Off-Peak: $0.15/$0.60 | Peak: $0.30/$1.20 | active |
| OpenRouter | deepseek/deepseek-v4.1-flash | 1.05M tokens (1,048,576) | 384K tokens (384,000) | $0.15 / $0.60 per 1M (Cache hit $0.003/M) | active |
| OpenCode Go | deepseek-v4-flash | 1M tokens (1,000,000) | 64K tokens (64,000) | Included with OpenCode Go subscription | active |
| OpenCode Zen | deepseek-v4-flash | 1M tokens (1,000,000) | 64K tokens (64,000) | Curated pay-per-token coding route | active |
| NVIDIA NIM | deepseek-ai/deepseek-v4-flash | 262K tokens (262,144) | 8K tokens (8,192) | NVIDIA NIM enterprise microservice | active |
| Cloudflare Workers AI | @cf/deepseek-ai/deepseek-v4-flash | 1.31M tokens (1,310,720) | 8K tokens (8,192) | $0.44 / $1.32 per 1M tokens (edge inference) | active |
| Cline / ClinePass | cline-pass/deepseek-v4-flash | 1M tokens (1,000,000) | 16K tokens (16,384) | Sponsored community route in Cline extension | free |
| OpenRouter (Batch) | deepseek/deepseek-v4.1-flash:batch | 1.05M tokens (1,048,576) | 384K tokens (384,000) | 50% off standard OpenRouter rates ($0.075/$0.30) | batch |
Synthesized via Fish Audio S2.1 Pro in British English. Natural editorial summary, not verbatim reading.
Key Takeaways
- check_circleDeepSeek released DeepSeek-V4.1-Flash on 10 September 2026. The model features 552B total MoE parameters with an asymmetric activation profile: 8B active parameters on prompt encoding and 16B on generation.
- check_circleNative visual understanding is built directly into the core model architecture, replacing the separate experimental vision routes (V4-Flash-Vision-Exp).
- check_circleKV cache footprint has been reduced to 1/4 HBM and 1/8 SSD requirements, directly driving down long-context and multi-turn agent operating expenses.
- check_circleAPI pricing introduces aggressive cuts: standard rates are $0.30/M input and $1.20/M output, with 50% discounts during off-peak hours ($0.15/M input and $0.60/M output). Cache hits drop to $0.006/M peak and $0.003/M off-peak.
- check_circleAIMI detected the production route deepseek/deepseek-v4.1-flash on OpenRouter at 08:42:58 SAST, shortly after the official announcement.
- check_circleDeepSeek confirmed that V4-Pro is being phased out, with all deepseek-v4-pro requests automatically rerouting to V4.1-Flash starting 14 September 2026 until V4.1-Pro arrives.
An asymmetric architecture designed for high-efficiency inference
DeepSeek announced DeepSeek-V4.1-Flash on the morning of 10 September 2026, rolling out the first member of its new V4.1 model family. Built on a 552-billion-parameter mixture-of-experts structure, V4.1 Flash incorporates a Causal Encoder–Decoder architecture with asymmetric parameter routing.
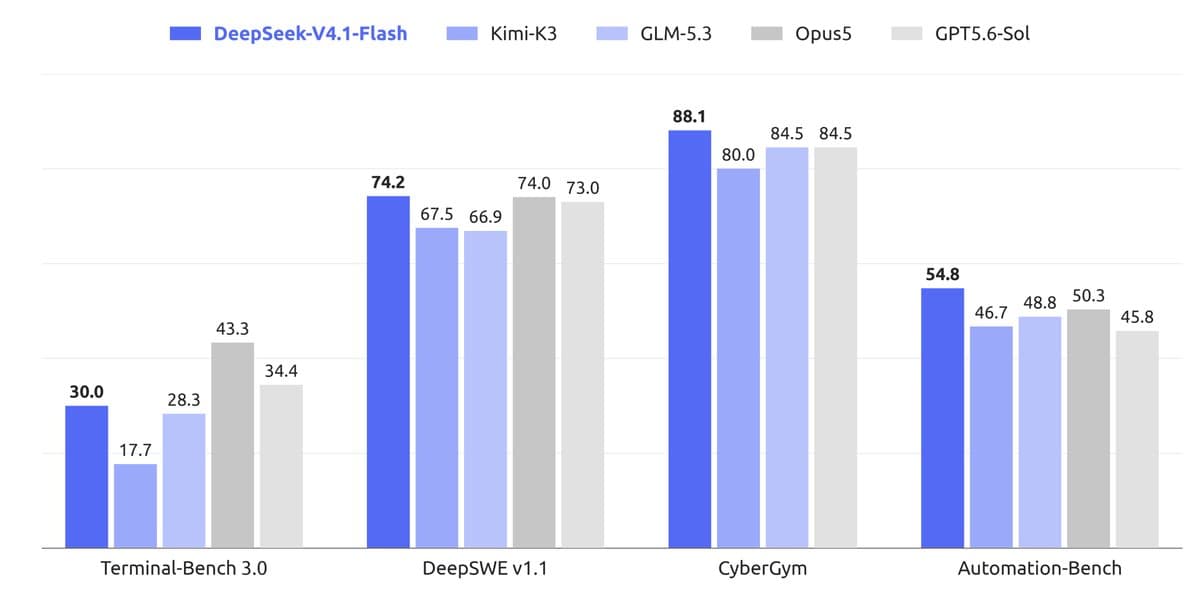
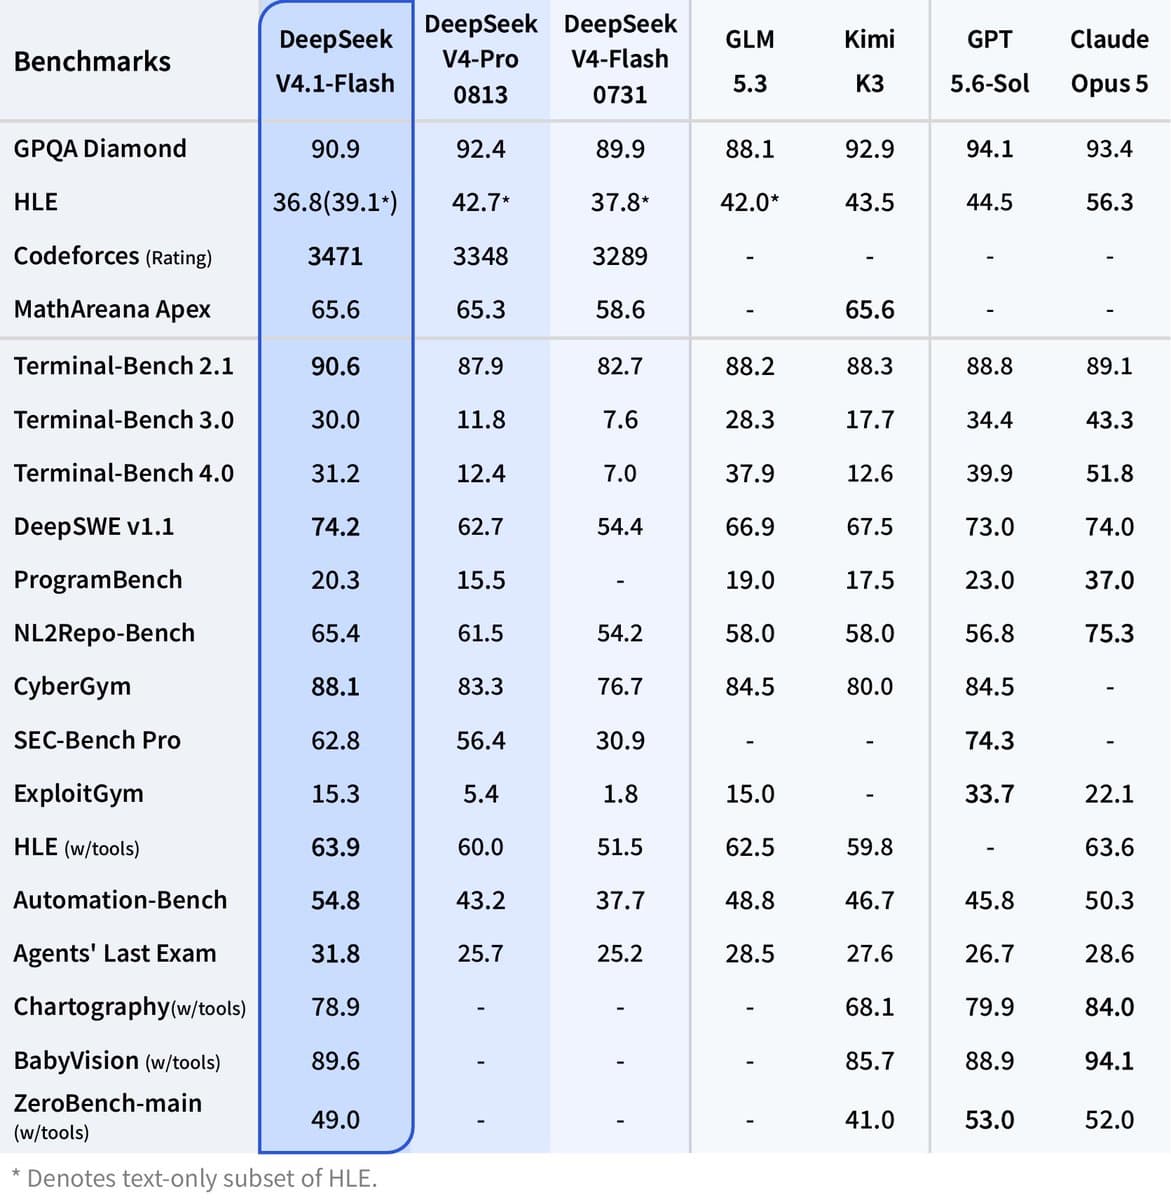
Instead of activating a static slice of weights across the entire sequence, the model engages only 8 billion active parameters during input comprehension, expanding to 16 billion active parameters during token generation. Combined with refined pre-training and scaled reinforcement learning, DeepSeek reports that V4.1 Flash outperforms its prior flagship DeepSeek-V4-Pro across core reasoning, coding, and multilingual benchmarks while running at significantly higher generation speeds.
Drastic KV cache compression cuts multi-turn agent expenses
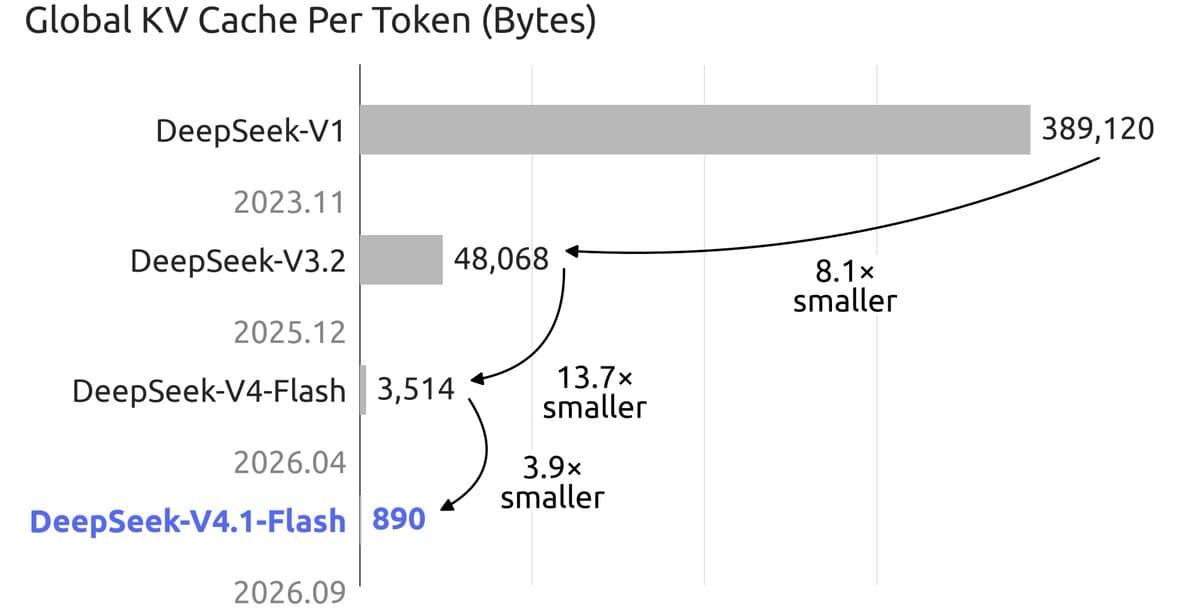
A persistent bottleneck in production agent systems is the memory and storage overhead of long-context key-value (KV) caches. For teams maintaining stateful conversation histories or running multi-turn tool loops, cache maintenance frequently dominates the monthly compute bill.
DeepSeek addressed this constraint directly in V4.1 Flash by re-engineering cache representation. According to official disclosures, the model requires just 25% of the High Bandwidth Memory (HBM) and 12.5% of the SSD storage needed by previous iterations. In practice, this allows inference providers to serve substantially higher concurrent context volume without hardware saturation.
Aggressive pricing and the retirement of DeepSeek V4-Pro
Alongside architectural efficiencies, DeepSeek instituted immediate price reductions on its first-party API, effective 04:00 UTC on 10 September 2026. Standard peak pricing sits at $0.30 per million prompt tokens and $1.20 per million completion tokens. During off-peak windows (and all weekend), rates drop by 50% to $0.15 per million input tokens and $0.60 per million output tokens. Cached prompt reads cost a mere $0.006 per million tokens peak and $0.003 off-peak.
Because internal and partner testing established that V4.1 Flash outpaces DeepSeek-V4-Pro in overall speed, quality, and cost efficiency, DeepSeek announced the scheduled retirement of V4-Pro. Starting at 04:00 UTC on 14 September 2026, existing deepseek-v4-pro API endpoints will automatically route traffic to V4.1-Flash at the new lower rates, serving as an interim solution until DeepSeek-V4.1-Pro completes training.
AIMI route discovery and developer availability
AZ Labs AI Model Intelligence (AIMI) recorded the live route deepseek/deepseek-v4.1-flash on OpenRouter at 08:42:58 SAST, approximately 32 minutes after the public release thread was posted. OpenRouter exposed full tool support, JSON structured outputs, and a 1,048,576-token context window.
Official ecosystem partners, including WorkBuddy and OpenCode, launched day-one support for V4.1 Flash. The open-source model weights, inference configurations, and technical technical report have also been published on Hugging Face and GitHub for self-hosted cluster deployments.
Official Launch Announcement
Verified announcement directly from the maker's official account on X.
Visual Architecture & Benchmarks
Official maker scorecard graphics, diagrams, and benchmarks. Click any image to inspect in full resolution.
Frequently Asked Questions
What is DeepSeek-V4.1-Flash?
DeepSeek-V4.1-Flash is a 552B parameter mixture-of-experts model from DeepSeek featuring an asymmetric Causal Encoder-Decoder architecture (8B active input, 16B active output parameters) and native visual multimodal support.
What are the official API rates for DeepSeek V4.1 Flash?
Standard rates are $0.30/M input tokens and $1.20/M output tokens. Off-peak hours and weekends receive a 50% discount ($0.15/M input and $0.60/M output). KV cache hits cost $0.006/M peak and $0.003/M off-peak.
What happened to DeepSeek V4-Pro and V4-Flash-Vision-Exp?
V4-Flash and V4-Flash-Vision-Exp have been retired as V4.1 Flash integrates vision natively. DeepSeek-V4-Pro is also being phased out; beginning 14 September 2026, all V4-Pro API calls will automatically redirect to V4.1 Flash at V4.1 Flash pricing.
What is the context window size on OpenRouter?
OpenRouter exposes deepseek/deepseek-v4.1-flash with a context window of 1,048,576 tokens and up to 384,000 maximum completion tokens.
Related Frontier Models & Releases
Explore verified specifications, benchmark results, and route pricing across alternative models in this class.
DeepSeek Releases V4 Flash Vision Exp for Multimodal Agent Work
DeepSeek has released V4 Flash Vision Exp, an experimental API model that adds image understanding to the V4 Flash family while keeping its text capabilities.
DeepSeek V4 Pro Reaches GA with Adjustable Reasoning and Responses API Support
DeepSeek has released the GA version of V4 Pro for its app, web service and API. The 0813 model adds adjustable reasoning, native Responses API support, and a later hosted route on NVIDIA NIM.
OpenAI Releases GPT-6 Astra: Next-Generation Flagship with 1.05M Context and Deep Multimodal Reasoning
OpenAI has officially launched GPT-6 Astra, its frontier flagship model featuring a 1,050,000-token context window, 128,000 max output tokens, and native tool-use for autonomous agent workflows.